
How to Archive Webhooks to Amazon S3 (Store Every Payload)
Store every incoming webhook in Amazon S3 with Service Connections — no code. Keep an auditable archive of payloads for compliance and debugging.
When a webhook drives something important — a payment, an order, a deploy — you eventually want a record of exactly what the provider sent, not just whether your handler succeeded. An archive in Amazon S3 gives you that: an auditable, replayable history of every payload. Webhook Relay Service Connections write webhooks to S3 for you, with no code.
How it works
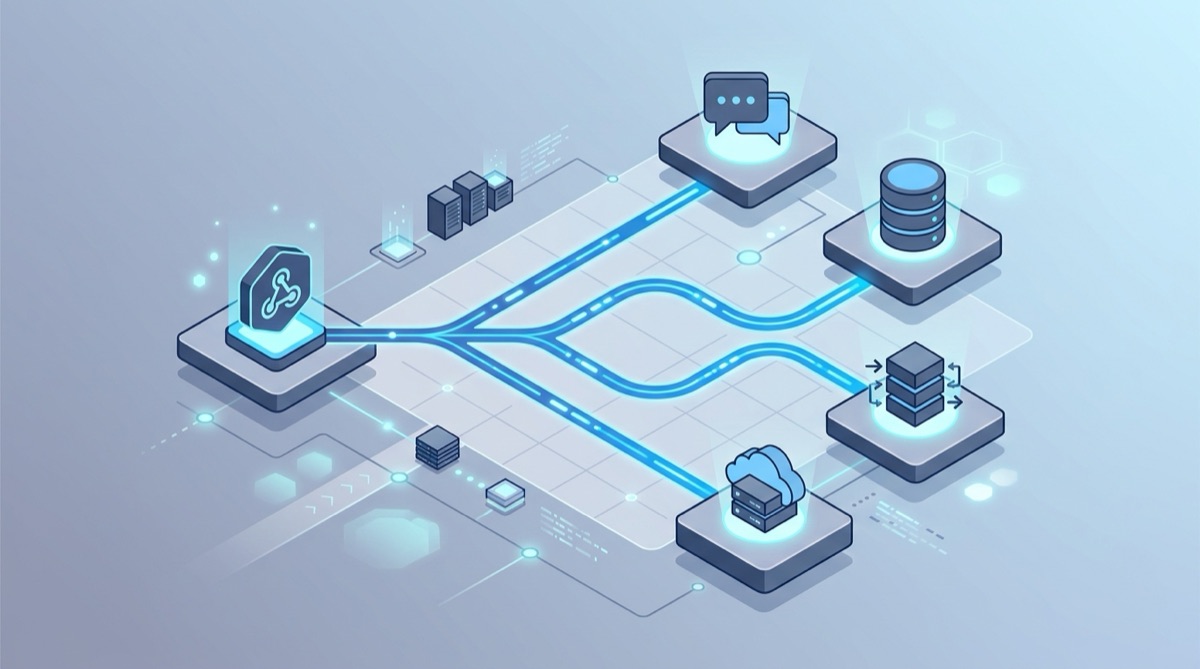
Webhook Relay has service connections (your cloud credentials) and outputs (where to send data). Attach an S3 output to a bucket, and every webhook that arrives is stored as an object:
Provider --> Webhook Relay bucket --> S3 output --> s3://your-bucket/...
This runs alongside your normal delivery — you can forward the webhook to your app and archive it to S3 at the same time.
1. Create an AWS service connection
Add a service connection for AWS with an access key whose only required permission is:
{ "Effect": "Allow", "Action": "s3:PutObject", "Resource": "arn:aws:s3:::my-bucket/*" }
Secrets are encrypted at rest (AES-256-GCM) and never returned in full by the API.
2. Attach an S3 output
Add an S3 output to the bucket that receives your webhooks:
- Bucket name and region (required).
- Prefix (optional) — e.g.
stripe/. - Format —
json(full webhook with headers, the default),body_only(raw body), orhar.
Objects are written under a dated key so they're easy to browse and lifecycle:
{prefix}/{year}/{month}/{day}/{log_id}.json
3. Point your provider at the bucket URL
Use the bucket's public Webhook Relay endpoint as the webhook URL in your provider, then test:
curl -X POST https://your-webhook-relay-endpoint \
  -H 'Content-Type: application/json' \
  -d '{"event":"invoice.paid","id":"in_123"}'
An object appears in S3 within seconds.
Why archive webhooks
- Audit & compliance. Keep an immutable record of what each provider sent, with retention via S3 lifecycle rules.
- Debug after the fact. Inspect the exact payload that caused a problem, even days later.
- Replay. Re-feed stored payloads into a new service or a rebuilt handler.
- Analytics. Point Athena or a data pipeline at the archive.
Going further
- Forward to your app and archive at once with multiple destinations.
- Transform or filter before storing.
- Need a queue or topic instead? See webhooks to SQS and webhooks to Pub/Sub. On Google Cloud, the same works with GCS.
Inspect a webhook first or create a free account to set up the S3 archive.